CAT3D Pounces on 3D Scene Generation

We very recently were looking at RealmDreamer, which generates scenes from prompts. Just over a month later, CAT3D, short for "Create Anything in 3D," has emerged and takes things up a notch or two.

We very recently were looking at RealmDreamer, which generates scenes from prompts. Just over a month later, CAT3D, short for "Create Anything in 3D," has emerged and takes things up a notch or two.

Michael Rubloff

Michael Rubloff

Michael is the Founder and Managing Editor of Radiancefields.com

CAT3D

We very recently were looking at RealmDreamer, which generates scene from prompts. Just over a month later, CAT3D, short for “Create Anything in 3D,” has emerged and takes things up a notch or two.

CAT3D leverages advanced multi-view diffusion models to generate highly consistent novel views from any number of input images going all the way down to one. These views are then processed using robust 3D reconstruction techniques to produce detailed 3D representations that can be rendered in real-time. Remarkably, CAT3D can create entire 3D scenes.

For all the impressiveness, there’s really two main steps to CAT3D’s approach: generating novel views and 3D reconstruction.
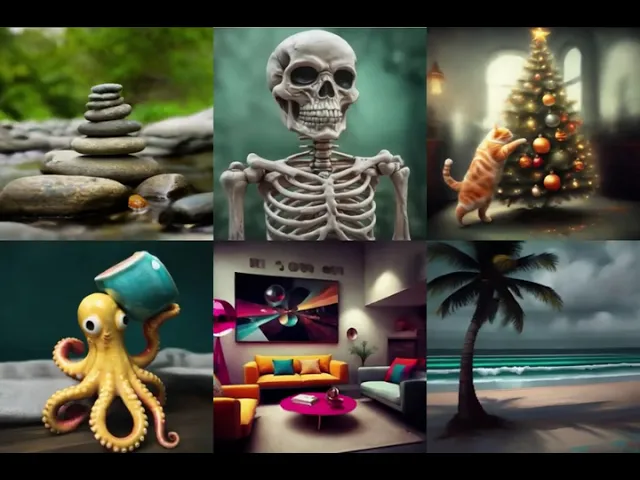
The model begins by taking conditional views as input, with each view comprising an image and its corresponding camera pose. Each input image is then encoded into a latent representation using an image variational auto-encoder. This transformation reduces the high-dimensional image data into a more manageable lower-dimensional latent space, facilitating easier processing by the model.

The diffusion model captures the joint distribution of target images based on their camera parameters. It predicts the latent representations of the target images from the input images and their camera poses. To ensure consistency among the generated views, the model employs 3D self-attention layers that connect the latents of multiple input images.

Camera poses are encoded using a raymap, which records the ray origin and direction at each spatial location. This representation is invariant to rigid transformations, ensuring that the generated views maintain accurate spatial relationships.

Once the multi-view diffusion model has been trained, it can generate a large set of synthetic views to cover the entire scene. This includes designing camera trajectories that ensure thorough and dense coverage of the scene. These trajectories must avoid passing through objects and maintain reasonable viewing angles. Four types of paths are explored: orbital, forward-facing circle, spline, and spiral trajectories.

The target viewpoints are clustered into smaller groups based on their proximity. The model generates each group independently, ensuring local consistency within each group and long-range consistency between groups.

For single-image conditioning, an autoregressive strategy is used. Initially, a set of anchor views is generated to cover the scene. Subsequent views are then generated in parallel, using the observed and anchor views as conditioning inputs.

If the base input is a single image, they look to generate 80 images to cover the area and when there’s more, that range falls around 460-960 images.

Unsurprisingly, they build upon Google’s in house NeRF method, Zip-NeRF, but with some additional modifications. They include a perceptual loss (LPIPS) between the rendered image and the input image, which helps in preserving textures and fine details, but also ignores potential inconsistencies. The losses for generated views are weighted based on their distance to the nearest observed view. This approach ensures that views closer to the input images have a greater influence on the reconstruction process.

Impressively, CAT3D can create full scenes in roughly about a minute. We need to recognize that the ceiling on this technology is still unknown. Only a year ago, reducing generation time from hours to a single hour was impressive, and that was for individual objects.

Cat3D also benchmarks to Reconfusion, which was an awesome paper from the Google team late last year, that explored diffusion priors. CAT3D exceeded ReconFusion’s fidelity in every experiment run.

CAT3D also benchmarks against ReconFusion, an impressive paper from the Google team last year that explored diffusion priors.

To train CAT3D, you do need 16 A100 GPUs, but I do not believe the takeaway is that you need a large scale workstation to run this. I continue to believe that these are very positive indicators of the ability of the methods to function and to be quickly optimized. With Google also recently announcing Veo, I have to imagine how the two might play into one another.

For more information visit the CAT3D project page. They additionally have some interactive demos of outputs that were converted to Gaussian Splatting for people to try out!
Featured

Recents

Platforms

Niantic Spatial Launches the Places Library of 100 Simulation-Ready Real-World Environments

Niantic Spatial launches the Places Library, 100 real-world environments shipped as USDZ packages pairing a Gaussian splat with a collision mesh for Isaac Sim.

Michael Rubloff

Oct 4, 2026

Platforms

Niantic Spatial Launches the Places Library of 100 Simulation-Ready Real-World Environments

Niantic Spatial launches the Places Library, 100 real-world environments shipped as USDZ packages pairing a Gaussian splat with a collision mesh for Isaac Sim.

Michael Rubloff

Platforms

Ronski Adds Source Trimming and Keyframe Extraction to 360 Splat Pro v1.5.0

360 Splat Pro v1.5.0 adds Trim Source in and out points and a fast Keyframes extraction mode, and fixes a sharp frames search window that reached seconds away.

Michael Rubloff

Oct 3, 2026

Platforms

Ronski Adds Source Trimming and Keyframe Extraction to 360 Splat Pro v1.5.0

360 Splat Pro v1.5.0 adds Trim Source in and out points and a fast Keyframes extraction mode, and fixes a sharp frames search window that reached seconds away.

Michael Rubloff

Platforms

PlayCanvas Speeds Up SOG Compression and Fixes PLY Reading in splat-transform v3.9.0

PlayCanvas splat-transform v3.9.0 speeds up GPU k-means for SOG compression on devices without shader-f16 and decodes big-endian PLY while rejecting ASCII.

Michael Rubloff

Oct 3, 2026

Platforms

PlayCanvas Speeds Up SOG Compression and Fixes PLY Reading in splat-transform v3.9.0

PlayCanvas splat-transform v3.9.0 speeds up GPU k-means for SOG compression on devices without shader-f16 and decodes big-endian PLY while rejecting ASCII.

Michael Rubloff

Platforms

Gaussian Splat Patch Brings Clone Stamp and Healing Brushes to Gaussian Splats in Blender

Gaussian Splat Patch is a free Blender 5.3 extension that erases, clone stamps and heals Gaussian splat scans, with hole bridging and non-destructive Restore.

Michael Rubloff

Oct 3, 2026

Platforms

Gaussian Splat Patch Brings Clone Stamp and Healing Brushes to Gaussian Splats in Blender

Gaussian Splat Patch is a free Blender 5.3 extension that erases, clone stamps and heals Gaussian splat scans, with hole bridging and non-destructive Restore.

Michael Rubloff

Trending Articles
  1. TRENDING
    Loading...
  2. TRENDING
    Loading...
  3. TRENDING
    Loading...
Michael Rubloff

Written by Michael Rubloff

Michael is the Founder and Managing Editor of Radiancefields.com

More from Michael Rubloff

More from Michael Rubloff

Platforms

Niantic Spatial Launches the Places Library of 100 Simulation-Ready Real-World Environments

Niantic Spatial launches the Places Library, 100 real-world environments shipped as USDZ packages pairing a Gaussian splat with a collision mesh for Isaac Sim.

Michael Rubloff

Oct 4, 2026

Niantic Spatial

Platforms

Niantic Spatial Launches the Places Library of 100 Simulation-Ready Real-World Environments

Michael Rubloff

Oct 4, 2026

Niantic Spatial

Platforms

Niantic Spatial Launches the Places Library of 100 Simulation-Ready Real-World Environments

Niantic Spatial launches the Places Library, 100 real-world environments shipped as USDZ packages pairing a Gaussian splat with a collision mesh for Isaac Sim.

Michael Rubloff

Oct 4, 2026

Niantic Spatial

Platforms

Ronski Adds Source Trimming and Keyframe Extraction to 360 Splat Pro v1.5.0

360 Splat Pro v1.5.0 adds Trim Source in and out points and a fast Keyframes extraction mode, and fixes a sharp frames search window that reached seconds away.

Michael Rubloff

Oct 3, 2026

360 Splat Pro

Platforms

Ronski Adds Source Trimming and Keyframe Extraction to 360 Splat Pro v1.5.0

Michael Rubloff

Oct 3, 2026

360 Splat Pro

Platforms

Ronski Adds Source Trimming and Keyframe Extraction to 360 Splat Pro v1.5.0

360 Splat Pro v1.5.0 adds Trim Source in and out points and a fast Keyframes extraction mode, and fixes a sharp frames search window that reached seconds away.

Michael Rubloff

Oct 3, 2026

360 Splat Pro

Platforms

PlayCanvas Speeds Up SOG Compression and Fixes PLY Reading in splat-transform v3.9.0

PlayCanvas splat-transform v3.9.0 speeds up GPU k-means for SOG compression on devices without shader-f16 and decodes big-endian PLY while rejecting ASCII.

Michael Rubloff

Oct 3, 2026

PlayCanvas

Platforms

PlayCanvas Speeds Up SOG Compression and Fixes PLY Reading in splat-transform v3.9.0

Michael Rubloff

Oct 3, 2026

PlayCanvas

Platforms

PlayCanvas Speeds Up SOG Compression and Fixes PLY Reading in splat-transform v3.9.0

PlayCanvas splat-transform v3.9.0 speeds up GPU k-means for SOG compression on devices without shader-f16 and decodes big-endian PLY while rejecting ASCII.

Michael Rubloff

Oct 3, 2026

PlayCanvas

New to Gaussian Splatting? Start here

Radiance fields, explained from the ground up: what a Gaussian splat is, how to capture one, and which tools and gear to start with.

Newsletter

Keep up with the field.

New research, tools and captures from the Radiance Fields newsroom, in your inbox. Free, no spam.